Week 4 of 8 · Networks half
Communities and seeing networks
Week 3 zoomed in on the single node. This week we zoom out one level, to communities. The groups of nodes that hang together: your family, workplace book club, and soccer team.
Before class
- Bring. Laptop, Python + Jupyter + NetworkX, your agentic coding tool. Wednesday 09:00 in Auditorium 43: a short pep-talk, the go-nuts winner from week 3, then you work this page top to bottom with me and the TAs around.
- This week's story in one line. Networks are made of groups; cut the links that carry the most shortest paths and a network falls apart into them; a number (modularity) says where to stop cutting; optimize that number directly and you get Louvain, fast but never the same answer twice; real groups overlap, and cliques and links can see it; and once links have weights you can strip a hairball down to its backbone and draw it honestly.
- Last content week before Test 1. Wednesday 30 September, first hour, covers weeks 1–4. The 🧠 exercises here are the shape of the questions. A pointer box at the end of the page collects the four Essentials bands.
1 · Communities
Communities are in the middle in the network. The smallest parts are nodes, we also have the whole network. And communities are in between. They are groups of nodes. We all have intuitions for them. Families, classmates, friend groups, workplaces, and so on, are all groups.
There are communities in other networks too, but we'll focus on social networks. Communities are so important that I've already kind of used them in the class. In week 1, when we talked about network visualization, I included communities in the visualization. And the cliques from last week are a kind of super-connected communities (more on that later).
Because I want to work on a network with strong community structure, we're dropping the Marvel network this week and switching to philosophers. The Marvel network does have community structure, but it's not super strong (Section 4 has the numbers), I'd like to find a network where you can actually see the groups.
The network I've chosen consists of every philosopher born before 1900 on Wikipedia's lists of philosophers by century. There's 1,444 of them, with a link wherever one article links to another, just as before.
The giant component holds 1,374 philosophers and 9,139 links, and the communities in it are systems of philosophy that you may have heard of: Greek antiquity, the medieval scholastics, German idealism, Indian and Chinese philosophy. Data, incl. a weight on every link, can be found on the data page.
There are thousands of papers on finding communities. Part of the reason is that nobody has ever agreed on a definition, so people can always just come up with a new one and write a paper. For years people argued that a community is a set of nodes that is densely interconnected and weakly connected to the rest of the network. (I've actually shown that sometimes even the mild definition above is too strict. It's actually only about being densely interconnected. But I'm getting ahead of myself. More on that later.)
But why are we even looking for communities? There are three reasons.
- Summary: The level of individual nodes is too detailed. The whole network is too broad. Eight or nine communities is a way to organize how the information in the network is structured.
- Meaning: A community helps you understand what's going on in the network. In the philosopher network we already discussed how the communities are the different systems (or schools) of philosophy.
- Visualization: When we color by community, that somehow helps us parse the network visually. And it looks cool ;)
Read
Network Atlas, Ch. 35 Graph Partitions, the introduction (two pages): what a community is, why the field disagrees with itself, and the map of the chapters that follow.
A lecture that captures the spine of this page: it covers five ideas in order, and Sections 2–6 below follow the same order (edge betweenness, modularity, optimizing modularity, k-clique communities, link communities, which take up about the second half). The video uses different example networks; treat it as the guided tour, the text below as the map. It's OK to watch it AFTER reading.
2 · Cutting the bridges: edge betweenness
Origin story. Even though we're not using the Marvel network, it's time for an origin story. I'm going to let you in on how community detection started. And there's a nice connection to last week: betweenness.
Back in 2002, Michelle Girvan and Mark Newman had an idea. As you recall from last week, betweenness is based on the number of shortest paths that run through a node. Give the same count to a link and you have edge betweenness: the number of shortest paths that run along it.
Girvan and Newman were trying to think about a network made of groups. Trying to think about how they could split it into the groups in an automated way. And they realized that links between groups would have high edge betweenness.
Here is the reason. Paths between two members of the same group stay inside the group, spread over its many links. Paths between two groups carry all of the "traffic" going between the two groups. So the bridges will all have high edge betweenness.
So the idea was this:
- Compute the edge betweenness of every link.
- Remove the link with the highest value.
- Recompute every value (because a removal reroutes the traffic: the paths that used the cut link now crowd onto the remaining bridges).
- Repeat.
As you run this simple algorithm, the network falls apart into groups, the biggest cuts first, and if you record the order in which groups split you get a tree, a dendrogram: the network's hierarchy of groups, from one blob at the root down to single nodes at the leaves.
A benchmark network with three planted communities of 28, 32 and 40 nodes. The violet link carries the most shortest paths (286.4) and goes first. Press Step a few times and watch the readout: every cut is a link between two planted groups, and as the bridges thin out the survivors carry more and more (by cut 13 the top value is over 1,000). Press Next split: cut 15 is the last link between a group of 68 and a group of 32, and it carries exactly $68 \times 32 = 2{,}176$ shortest paths, one for every pair across. Right after the split the recomputed values drop to 183. Press Next split again: cut 27 leaves the three planted groups, and the strip under the dendrogram marks that level as the best one, $Q = 0.571$ (Section 3 explains $Q$). Then Play, and watch the groups crumble.
The Zachary Saga. The first network Girvan and Newman tested it on is the most famous small network there is, and it deserves its own digression. In the early 1970s the anthropologist Wayne Zachary spent three years watching a university karate club. It had 34 members, an instructor known in the paper as Mr. Hi, and a president, and the two of them had a serious disagreement over the price of lessons.
As an anthropologist, Zachary had hit the jackpot. He had chosen to study a random karate club, and then something really exciting happened. The club split into two factions. Now Zachary had an exciting paper to write.
But from the perspective of network science Zachary also brought something to the table. He had recorded who was friends with whom outside the club: 34 nodes, 78 links. And he asked his network nodes who they supported in the feud. And you can see it right there in the network. Two communities, split right down the middle.
Anecdote 1: The network structure only got it almost right. It got 33 of the 34 right. The one miss was a member who sided with the instructor for a reason no network could see: he was three weeks from his black-belt exam and did not want to start over.
Girvan–Newman's first cut on the club is the friendship between Mr. Hi (member 0) and member 31, with edge betweenness 71.4, far ahead of the next link at 43.8. After 11 cuts the club has fallen into two groups of 19 and 15, wrong about only two members, one of them the black-belt student. You can see the network down in Section 3's explorable.
And this network somehow became the "fruit fly" of community detection, used in hundreds upon hundreds of papers. In part because it had ground truth. Zachary had labeled the two communities, so we knew what the groups should be. That information usually is not available for most networks.
Anecdote 2: In fact, the network became so overused that network scientists started a running joke: at any network conference, the first speaker to put the karate club on a slide is inducted into the Zachary Karate Club Club and handed a trophy to keep until the next conference. The idea was Aaron Clauset's; the tradition began in 2013 at the Santa Fe Institute, and the first holder was the physicist Cristopher Moore.
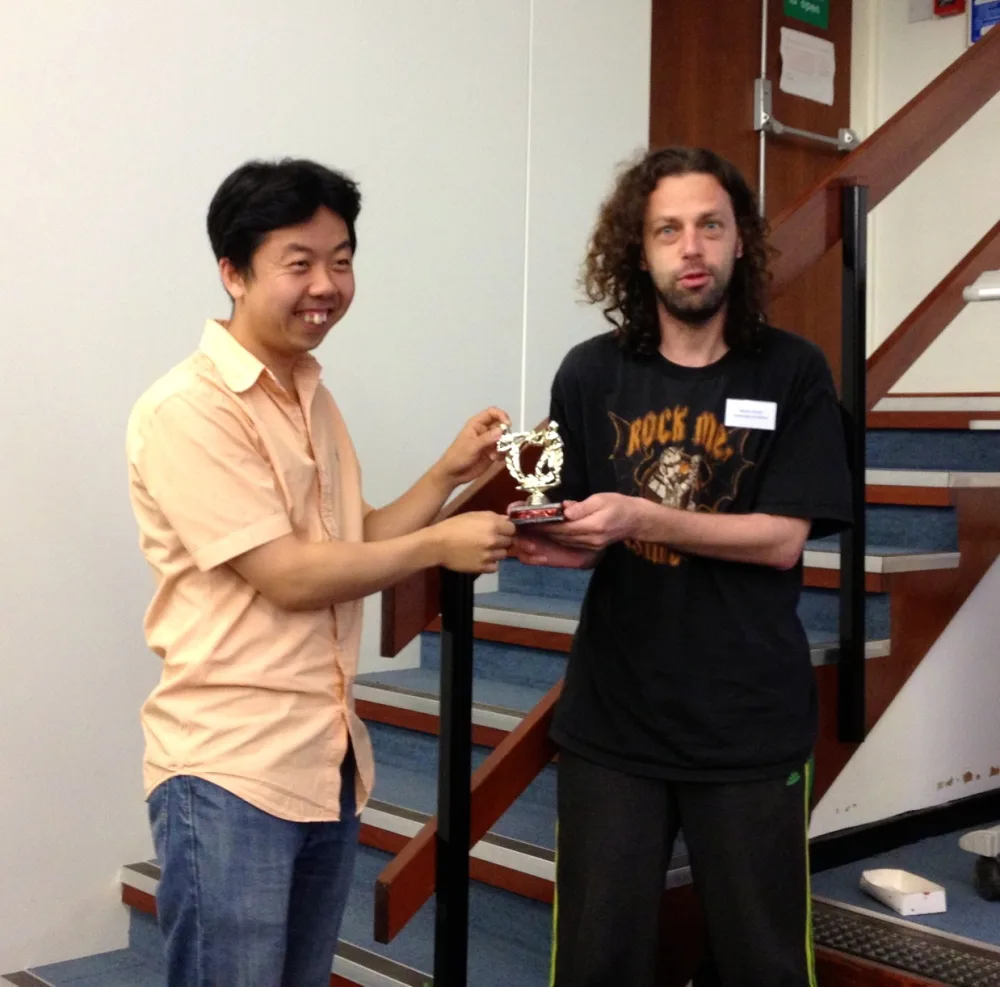
Inductee #3 collects the prize: my friend and collaborator YY Ahn (left) takes the trophy from Mason Porter (right, inductee #2) for putting the karate club on a slide at the Oxford Workshop on Time-Dependent and Multiplex Networks, July 2013. Photo: the Zachary Karate Club Club.
The Girvan–Newman algorithm is beautiful, so why didn't people just use that and be done with it? See if you can guess. The answer is that it is slow. Way too slow to use in practice.
Every cut needs a full recomputation of edge betweenness, which means a shortest-path search from every node, and there is one cut per link: $O(m^2 n)$ in total. On the karate club that is nothing. On the philosophers, a single edge-betweenness pass takes about five seconds in networkx on my laptop which is pretty decent, and a full run needs one pass for each of the 9,139 links: hours of computing to find groups that Section 4 finds in a second. It's available in networkx as girvan_newman.
Read
Network Atlas, Ch. 37 Hierarchical Community Discovery, section 37.1 Recursive Approaches, the part called Splitting: Girvan–Newman with a worked example. (Edge betweenness itself is in section 14.2, from week 3.)
4.1 — Cutting by hand 🧠 Learn
Draw this network: nodes A–G, links A–B, A–C, B–C, C–D, D–E, D–F, E–F, F–G. ($m = 8$.) Exercises 4.3 and 4.10 use it again.
- Compute the edge betweenness of every link by counting. There are 21 pairs of nodes; for each pair find the shortest path and add 1 to every link on it (this network has no ties, so no pair has two shortest paths). Some links are quick: C–D carries every path between {A, B, C} and {D, E, F, G}. Which link does Girvan–Newman remove first?
- Remove it and recompute. Which values changed? Explain in one sentence why F–G's value is now half what it was.
- Remove the next link. Draw the first two levels of the dendrogram: which groups appear at level 1, and which at level 2?
- Why does Girvan–Newman recompute after every removal instead of computing edge betweenness once and removing the links in that order? Point to the moment in the explorable where it matters.
3 · A dendrogram isn't really communities: modularity
A dendrogram isn't really communities. If you look at the explorable up in Section 2, you'll see that what you really get is a recipe for splitting up the network part by part. So what's the best way to split it up, where should you cut the dendrogram?
In a follow-up paper in 2004, Newman and Girvan proposed a measure of how community-like a specific partitioning of a network is so you can decide in a quantitative way. A recipe to score the groups at every single level, and cut where the score is highest. The number is modularity, and it turned out to do its job well. So well in fact, that it became a whole thing in its own right — much more than Girvan and Newman originally thought it would be (much more on this below).
Modularity is a way to score a proposed split. To get started, let's take the karate club, where we know the answer, and count the links that fall inside groups: in Zachary's real split, 67 of the 78 friendships stay within a faction, and only 11 cross. That sounds like a lot, but (as last week) compared to what? If you shuffled the friendships at random while keeping everyone's number of friends (the degree-preserving null from week 2, the configuration model), how many would land inside the same two groups by chance alone?
The expected number of links between nodes $i$ and $j$ under that null is $k_ik_j/2m$. If you subtract that number from the actual number of links, you have modularity:
$$Q = \frac{1}{2m}\sum_{ij}\left(A_{ij} - \frac{k_ik_j}{2m}\right)\delta(c_i, c_j),$$
where $\delta(c_i, c_j)$ is 1 when $i$ and $j$ are in the same community and 0 otherwise.
In words modularity is the fraction of links inside communities, minus the fraction you would expect within communities by chance, given the degrees. For hand computation the same quantity per community $c$ is
$$Q = \sum_c \left[\frac{\ell_c}{m} - \left(\frac{d_c}{2m}\right)^2\right],$$
where $\ell_c$ is the number of links inside community $c$ and $d_c$ the sum of the degrees of its members.
And modularity has some nice properties. Putting all nodes inside a single community gives $Q = 0$ exactly; a random assignment of nodes into communities also gives you $Q \approx 0$, and a partition where links are only inside groups and rarely cross can yield a $Q$ up to a theoretical 1. Real networks with clear groups tend to land somewhere between 0.3 and 0.7 depending on the network.
Zachary's real split scores $Q = 0.358$.
With modularity in place, we have a strategy for how to cut the dendrogram. We simply check the value for every single partition and pick the best one. On the karate club, Girvan–Newman's two groups score $Q = 0.360$, but the best level of its dendrogram is five groups, $Q = 0.401$, after 24 cuts. More in the explorable below. (On the benchmark in Section 2's explorable, the best level is exactly the three planted groups.)
The club, colored by Zachary's real split: $Q = 0.358$, 67 of 78 friendships inside the two groups, 39 expected by chance. Click member 2 to move them across and $Q$ drops to $0.329$; click member 8, the one Zachary's model got wrong, and it rises to $0.372$; click member 0 (Mr. Hi himself) and it collapses to $0.166$. Press Best two-way split for the partition that beats the real one, and Louvain for four groups the club never had, at $Q = 0.420$. Then Shuffle members and see where chance lands. The strip on the right is the landscape you are walking on.
There are two important things that the explorable shows that the formula does not. First, $Q$ is not maximized by Zachary's ground truth. Moving member 8 to the other side raises $Q$ (he has more friends there; remember that the black-belt exam was the reason he stayed), and a four-group split scores higher than the real two factions (because each faction had an inner circle). Modularity measures how grouped a partition is, not how right it is; there is no "right" inside the number. Second, the landscape is full of near-ties: many different partitions have almost the same modularity. In other words, in spite of many nice qualities, modularity has lots of issues and isn't necessarily always used to detect communities nowadays. We will discuss those issues in detail below.
Read
Network Atlas, Ch. 36 Community Evaluation, section 36.1 Modularity. Two pages of definition and one of caveats; the caveats come back in Section 4.
4.2 — Did you really read it? — groups 🧠 Learn
No notebook, no chatbot. Think, then write.
- Define a community in one sentence, then explain why "the nodes that are all connected to each other" is not a good definition (what would it say about the philosophers?).
- Why does modularity subtract $k_ik_j/2m$? What would go wrong if you scored a partition by the fraction of links inside communities alone? (Hint: what does that fraction give when everyone is in one community?)
- In the karate club, Louvain's four groups score higher than the real two factions. Does that mean the four groups are "more real"? What does it mean?
- A friend reports "modularity 0.35, so the network has community structure." List the two questions you would ask before believing it.
4.3 — Modularity by hand 🧠 Learn
Use the network from exercise 4.1: nodes A–G, links A–B, A–C, B–C, C–D, D–E, D–F, E–F, F–G ($m = 8$).
- Compute $Q$ for the partition {A, B, C} · {D, E, F, G} using the per-community formula: for each group, count the links inside it and add up its members' degrees.
- Compute $Q$ for the partition {A, B, C, D} · {E, F, G}. Which of the two is better, and by how much? Explain in one sentence, from the network drawing, why.
- Compute $Q$ for level 2 of your dendrogram from exercise 4.1. Which level of the dendrogram would Newman and Girvan cut at?
- Compute $Q$ for "everything in one community." Then argue, without computing, whether any partition of this network can score below that.
- Node G has degree 1. Show that moving G into the same community as F always raises $Q$. (This is the reason community detection sticks leaves to their only neighbor.)
4.4 — Thousands of modularity papers? 🚀 Builder · optional
I've claimed that there are thousands of papers about modularity. Am I right? Use your agentic powers to find out, and end with a number you can defend. Google Scholar has no API (and blocks scrapers), so use OpenAlex, the open index of scholarly works: https://api.openalex.org/works?... answers in JSON, the hit count is in meta.count, and per-page=1 keeps each call small. No key is needed for about a hundred searches a day; a free key from openalex.org raises that tenfold.
- Count three ways and compare: all text (
search=modularity), titles only (filter=title.search:modularity), and titles and abstracts that also name the method (filter=title_and_abstract.search:modularity AND "community detection"). How far apart are the answers? - 🔬 Validate before you believe: pull 20 random hits from each query (
sample=20&seed=1) and read the titles. What fraction is about modularity in our sense? (Search engines stem words: what else does a query for "modularity" match?) Turn that into an estimate with an honest range. - A different definition: count the papers that cite Newman and Girvan's 2004 paper, the one that defined $Q$ (look it up by DOI with
works/doi:10.1103/PhysRevE.69.026113, then usefilter=cites:plus its id), and do the same for the Louvain paper. Which count answers my question better, and what does each one miss? Addgroup_by=publication_yearto your best query for a papers-per-year curve: is modularity a finished topic or a live one?
4 · Optimizing modularity: from greedy merging to Louvain
At some point Mark Newman realized that you don't need the dendrogram at all. If $Q$ is a measure of how good communities are, why not just find the split of the network that optimizes $Q$ directly? It turns out that this is a really difficult optimization problem because there are many ways to split up a network into partitions. For our example network with the philosophers, the number of ways to partition 1,374 nodes is a number with 2,804 digits, and finding the maximum exactly is NP-hard.
So Newman didn't attempt to truly optimize $Q$. In a second 2004 paper, instead, the idea is to basically run Girvan–Newman backward. Start with every node in its own community. Of all the pairs of communities that share a link, merge the pair whose merge raises $Q$ the most. Record $Q$, and repeat until everything is one community; then keep the level where $Q$ was highest. That is a dendrogram built bottom-up, where Section 2's was top-down, and it is fast, because the change in $Q$ from one merge depends only on the two communities involved. It is also greedy: a merge is never undone, so an early merge that looked good locks in its mistake.
On the philosophers, networkx's version (greedy_modularity_communities, a faster implementation of the same rule by Clauset, Newman and Moore) finds 15 communities with $Q = 0.416$: three giant blobs of 550, 481 and 262 philosophers, one of them Heraclitus and Plotinus together with Bertrand Russell and Albert Einstein, plus a dozen small groups. Greedy optimization is almost never great. In this case, early merges snowball, and the big communities cannot be taken apart again.
So I mentioned there were a lot of modularity papers, and many of those are simply clever ways to climb the modularity landscape without seeing all of it.
But in 2008, researchers came up with a method that is good enough. It is the algorithm everybody still uses, and the team behind it was Vincent Blondel and three colleagues at the Université catholique de Louvain, in Belgium, and the algorithm is named after the town. One of the three, Renaud Lambiotte, was a guest on my podcast; the Louvain story starts at 28:38, t-shirt included. It is embarrassingly simple and super fast, and I think the speed has something to do with its popularity. The Louvain algorithm also fixes greedy merging's worst habit by allowing single nodes to change community. It works like this.
Phase 1: move nodes. Start with every node in its own community. Visit the nodes one by one. For each node, try moving it into the community of each of its neighbors, compute the change in $Q$ each move would cause, and make the best move if it raises $Q$; otherwise leave the node where it is. Sweep through all nodes, then sweep again, until a whole sweep moves nobody.
Phase 2: aggregate. Collapse each community into a single super-node. Links between two communities become one weighted link (weight = how many links crossed); links inside a community become a weighted self-loop. Now you have a smaller network. Go back to phase 1 and run it on that.
Repeat until phase 1 moves nothing. The communities of the last level, unpacked back to the original nodes, are the answer. Because each move only touches one node and its neighbors, one sweep costs about as much as reading the edge list once, and Louvain runs on networks with hundreds of millions of links. Watch it work on the philosophers:
Press Step a few times: one philosopher at a time joins a neighbor's community and $Q$ ticks up. Then press Sweep twice: two passes over all 1,374 philosophers make 1,794 moves and leave 165 groups at $Q = 0.380$, past the dashed line at $0.228$ that a shuffled network reaches (the line is crossed at move 1,226). Press Aggregate: phase 1 finishes (65 groups, $Q = 0.458$) and the groups collapse into 65 super-nodes. Then Play: the second level needs only 73 more moves, and the third just two, to reach 8 communities and $Q = 0.506$, where no single move can improve anything.
Run to the end, the explorable finds 8 communities with $Q = 0.506$. If we name them after their highest-degree member (as the legend does), we can now read and see a connection to the history of philosophy. Aristotle's group is Greek and Roman antiquity (Plato, Cicero, Heraclitus, Socrates). Thomas Aquinas's is Christian thought from Augustine through Dante to Luther and Erasmus. Immanuel Kant's is German philosophy from Schelling and Hegel to Marx and Nietzsche. René Descartes's is early modern Europe and the Enlightenment (Leibniz, Spinoza, Locke, Hume, Voltaire). Bertrand Russell's is the generation that founded 20th-century philosophy (William James, Peirce, Bergson, Wittgenstein, and Albert Einstein). The Buddha's is Indian philosophy, and Confucius's is Chinese philosophy, Mao Zedong included. The group named after Avicenna puts the medieval Islamic and Jewish philosophers (Averroes, Maimonides, al-Ghazali) together with Galileo, Copernicus and Francis Bacon, which is not a school anyone would name. You can construct a story for the communities we found (Greek science reached the Renaissance through Arabic translations and commentaries), but notice that you would be constructing it. That's a key distinction: the names are labels of the partition, while the story is what one tells afterward as we interpret the data.
Compared to what? Louvain finds $Q = 0.51$ on the philosophers. Is that a lot? I did say that values between 0.3 and 0.7 were what we would find in networks with community structure. But we can do better.
Can we use the null models that I introduced in Week 2? Let's shuffle and see. We can take the same 1,374 philosophers and 9,139 links, rewire them with the degree-preserving shuffle, and run Louvain on the result. Twenty shuffles give $Q = 0.228 \pm 0.002$. A completely random network with the same $n$ and $m$ gives $0.233$.
You can learn two things from this. Firstly, what we set out to learn. The philosopher network does indeed have communities. But, secondly, we see that the modularity of a random network is not zero!
A random network has no communities by construction, and Louvain still finds a partition with $Q = 0.23$, because with thousands of links there is always some way to draw group borders that cross fewer links than expected, and an optimizer is built to find it. (Roger Guimerà, Marta Sales-Pardo and Luís Amaral pointed this out in 2004, and it is still the most common mistake in reports that quote a modularity; Marta and Roger are an episode of my podcast, on Bayesian statistics and how they became scientists.) And how high can a network with no communities score? Much higher than $0.23$, it turns out: the sparser the network, the easier it is to find borders that few links cross, and a random network with an average degree of 2 reaches $Q \approx 0.8$. Exercise 4.6 has you map this out, and it is why Section 3's "0.3 to 0.7" is a rule of thumb and not a test.
How stable? If we run Louvain on the philosophers with ten different seeds (the order nodes are visited in phase 1 is random) we get different solutions. Somewhere around 8, 9 or 10 communities with $Q$ between $0.500$ and $0.508$.
Notice that $Q$ is almost the same in spite of quite different splits of the network (partitions).
To understand this phenomenon, we need a number for how much two partitions agree, and the standard one is the normalized mutual information (NMI). It is calculated as follows: treat each partition as a labeling of the nodes, compute how much knowing one label tells you about the other, and scale so that identical partitions give 1 and independent ones give 0. In symbols: with $n$ nodes, $n_x$ the size of community $x$ in the first partition, $n_y$ the size of community $y$ in the second, and $n_{xy}$ the number of nodes in both, the mutual information is $I = \sum_{x,y} \frac{n_{xy}}{n} \log \frac{n\, n_{xy}}{n_x n_y}$, and $\mathrm{NMI} = 2I / (H_1 + H_2)$, where $H = -\sum_x \frac{n_x}{n} \log \frac{n_x}{n}$ is each partition's entropy (the mutual information of a partition with itself). networkx has no NMI function; use sklearn.metrics.normalized_mutual_info_score(labels_a, labels_b), whose default is exactly this formula. Between two Louvain runs on the philosophers (seeds 0 and 1), NMI is $0.76$; across all 45 pairs of the ten runs it ranges from $0.65$ to $0.83$.
The runs agree on most of the split of the network, but disagree at the borders of communities. Descartes and Locke share a community in eight runs out of ten, Avicenna and Galileo in three (and in the explorable's run), and in one run Aristotle leaves Plato for Thomas Aquinas and the scholastics.
On Marvel, NMI between two runs is $0.59$: the partitions agree about as much as they disagree. That is one reason this week uses the philosophers rather than Marvel. Here's another key thing to remember. Because many different partitions can have similar modularity, never think of a partition as the "truth," it's more like a sample of what communities could be. Consensus between many runs is more stable and powerful. The sparse random networks from before make the point sharply: a random network with an average degree of 5 scores $Q = 0.45$, squarely in the range of real networks, and two Louvain runs on it agree at an NMI of about $0.2$. A high $Q$ with a low NMI is a score without a structure behind it (exercise 4.6 again).
Ground truth revisited Remember that part of what made Zachary's network popular was the ground truth communities? Well, here's an idea for how to use ground truth about communities.
When you have ground-truth labels, you can compare your partition to the ground truth labels via NMI. The philosophers come with a kind of label: the node file's era column says which century list each philosopher is on. NMI between the partition and the century is $0.40$, so we can learn that the communities are traditions, not centuries. Wikidata's "movement" label (stoicism, scholasticism, German idealism, for the 315 philosophers who have one) does better, $0.49$. And that's a finding about metadata, or "ground truth": it's not really the truth either. It is more like someone else's reading of the same people. If three checks on one number feels like a lot of patching, you are not alone: the Goodies box Peixoto's war on modularity makes the case for dropping modularity altogether, and says what to use instead.
From an AI-drafted report
"Louvain detected 9 communities with a modularity of 0.50, proving that the history of philosophy divides into nine schools." Three flaws, in one sentence each. There is no null model: a shuffled network scores 0.23, and without that number the reader cannot tell a strong result (this one is) from a weak one (Marvel's $0.38$, of which a shuffled network reaches $0.25$). There is no stability check: other seeds give 8 or 10 communities that agree with this run at NMI 0.65–0.83, so "the nine" are one run's nine. And "schools" is a story told after the fact: one community puts Avicenna with Galileo, and the partition agrees with the century lists at an NMI of only 0.40.
Read
Network Atlas, Ch. 37, section 37.1 Recursive Approaches, the part called Merging: greedy merging and Louvain, with the two phases drawn out. Then Ch. 36, section 36.4 Normalized Mutual Information; skim 36.2 Other Topological Measures for what else people score partitions with.
4.5 — Louvain on the philosophers, as code 🔬 Tool
- Load the philosophers network (the data page has the snippet), take the giant component of the undirected version, and run
networkx.community.louvain_communities. Report the number of communities and $Q$ (networkx.community.modularity). Check that your numbers are in this page's range. - For each community print its five highest-degree members, then name it in a few words. Which groups are easy to name? Which ones resist? Then compute the NMI between your partition and the
eracolumn, and between your partition and thesubfieldscolumn (use "none" for the empty ones). Which label does the partition know more about? - Run Louvain again with five different seeds. Report the number of communities and $Q$ for each. Then compute the NMI between every pair of runs and show the 5 × 5 matrix. What is the lowest agreement between two runs of the same algorithm on the same data? Which philosophers change community most often?
- Run
networkx.community.greedy_modularity_communities(Newman's greedy merging) on the same network. Report the communities, $Q$, and the NMI against your Louvain run, and explain from the two algorithms' descriptions why greedy merging scores lower. - 🔬 Have your agent implement phase 1 of Louvain from the description above (no community package), run it on the karate club, and validate that its $Q$ equals what
networkx.community.modularityreports for the same partition. Then make it explain why its partition can differ fromnetworkx's and still be "correct."
4.6 — Compared to what, and how stable 🧠 Learn + 🔬 Tool
- 🧠 Louvain has two phases. Say what each does in one or two sentences, and say what makes the result depend on the seed. Then: two Louvain runs on the same network give $Q = 0.505$ and $Q = 0.506$. Can you conclude they found nearly the same communities?
- 🧠 Why is the modularity of a random network greater than zero? Which null should you compare a modularity against, and why is it the degree-preserving one rather than $G(n, m)$?
- Shuffle-test $Q$ on the philosophers: 20 degree-preserving shuffles, Louvain on each, the mean and standard deviation, and the $z$-score of your real $Q$. Then do the same with 20 $G(n,m)$ networks and explain the difference between the two null values.
- 🔬 How high can a network with no communities score? Generate $G(n, p)$ networks with $n = 1{,}000$ and average degree $\langle k \rangle = p\,(n-1)$ from 1 to 50, run Louvain on each, and plot $Q$ against $\langle k \rangle$; then fix $\langle k \rangle = 3$ and vary $n$ from 100 to 10,000. Which parameter matters, and what is the highest $Q$ pure noise can reach? (A sparse random network has isolates and small components, and each one is a free community: decide whether to keep them or take the giant component, and say which you did.) Then run Louvain twice on each network with different seeds and compute the NMI between the two runs. Find the random network whose $Q$ matches the philosophers' $0.51$ and compare its NMI to the philosophers' $0.65$–$0.83$: what does the stability check see that the score does not?
- The karate club, as code: load
networkx.karate_club_graph(), build the real split from theclubnode attribute, and compute its $Q$. Watch out: thenetworkxkarate graph carries Zachary's edge weights, andmodularityuses them unless you passweight=None. Report both numbers and explain what the difference means. Then run Louvain (also withweight=None) and compare its partition to the real split by NMI. - 🧠 Rewrite the AI-drafted report above in three honest sentences: the value, the comparison, and what the partition does and does not establish.
5 · Overlap I: k-clique communities
But modularity isn't the only way to find communities. It's just one way of thinking about them. Below we discuss the first steps in a new direction.
$k$-clique communities. Everything so far assumed that a node belongs to exactly one community. But is that really the case in real networks? Take Aristotle. He is the center of Greek philosophy. But he is also the authority of the medieval scholastics (Aquinas calls him simply "the Philosopher"), and he turns up in almost every tradition since. Any partition of the nodes has to put him in only one of those and get the others wrong. And the same is true of people in real social networks: you are part of a family, a workplace, a soccer team, and placing you in only one of those communities would be just plain wrong.
The first method built for overlap is based on cliques. It was proposed by Gergely Palla, Imre Derényi, Illés Farkas and Tamás Vicsek in 2005. You need one more concept beyond the clique, clique adjacency. Let's call a clique of size $k$ a $k$-clique. Then we say that two $k$-cliques are adjacent if they share $k - 1$ nodes.
And we define a k-clique community as a connected set of adjacent $k$-cliques.
At $k = 3$, press Step: a triangle tips onto a neighbor it shares a side with, and the community grows one clique at a time. E ends up in both communities (two colors), K in none. Then switch to $k = 4$, $5$ and $6$ and watch who drops out.
For $k = 3$, picture a triangle tipping over one of its sides onto the next triangle. Two triangles that share only a single node are not adjacent, so that node can sit in two communities at once; and a node that is in no $k$-clique is in no community at all. The result is not a partition twice over: communities overlap, and some nodes are left out. The group released the method as software, CFinder, which finds the communities and draws them; in Python it is networkx.community.k_clique_communities(G, k). Note that this definition also means that not every node is a part of a community. In 3-clique communities you have to be part of a triangle, etc.
The size $k$ acts as a kind of community resolution. Let me illustrate via the philosophers:
| k | communities | largest | philosophers in a community | in two or more |
|---|---|---|---|---|
| 3 | 19 | 1,155 | 1,189 (87%) | 29 |
| 4 | 36 | 817 | 909 (66%) | 86 |
| 5 | 40 | 467 | 555 (40%) | 112 |
| 6 | 39 | 171 | 304 (22%) | 86 |
At $k = 3$ almost everything is connected in one giant community: triangles are everywhere, many of them share a dyad. It is a percolation transition, the same kind as week 2's random graph, and that is how Palla and colleagues described it. At $k = 4$ separate traditions break off: 31 Chinese philosophers, 16 Islamic theologians, 8 of the Vedanta school. At $k = 5$ the rest are small, sharp schools: the Church Fathers, the Legalists of ancient China (Han Fei, Shang Yang), the Russian religious philosophers, the Neo-Confucians. At $k = 6$ fewer than a quarter of the philosophers are in any community. And the overlap nodes are the hubs: at $k = 5$, Aristotle is in six communities, Augustine, Aquinas and Nietzsche in five each. There is no right $k$; report the one you chose, as you would any parameter.
Read
Network Atlas, Ch. 38 Overlapping Coverage, section 38.3 Explicit Structural Approaches, the part called Clique Percolation (two pages).
4.7 — Cliques on paper 🧠 Learn
Draw two triangles, {A, B, C} and {C, D, E}, sharing the node C, plus one extra link A–F.
- Any partition of the nodes puts C in one triangle. Compute $Q$ for {A, B, C} · {D, E} · {F} and for {A, B} · {C, D, E} · {F}. Which scores higher? Whichever wins, what does each partition get wrong about C?
- List every 3-clique. With $k = 3$, which of them are adjacent, and what are the k-clique communities? Name the node that is in two communities, the node that is in none, and the link that belongs to no community.
- Add the link B–D. List the 3-cliques again and find the $k = 3$ communities. What happened, and why is this percolation in miniature? What does $k = 4$ give?
- On the philosophers, $k = 3$ puts 1,155 philosophers in one community and $k = 6$ leaves 78% of them out. Explain each in one sentence.
6 · Overlap II: link communities
My favorite road to overlap, comes from a 2010 paper by Yong-Yeol Ahn, James Bagrow and Sune Lehmann (yes, that one). There's something appealing about that author team, can't quite put my finger on it. YY is also the trophy-holder in Section 1 and my guest on the podcast about doing research with Claude Code). What we notice in that paper is that while a nodes often participate in many contexts, link are typically much more unambigous.
So what happens if we cluster the links? Family links with family links, work links with work links, etc.
In the paper we argue that two links that share a node, $i$–$k$ and $j$–$k$, are similar if the neighborhoods of $i$ and $j$ overlap (a kind of Jaccard-style score: the neighbors they share, over the neighbors either has).
Now that we have a similarity, we can cluster links by that similarity, and each cluster of links is a link community. Then every node inherits all the communities its links belong to. A node with links in three link communities is in three communities, at no extra cost, and the overlap is a natural part of the method instead of being bolted on. The second half of the video lecture in Section 1 is this method, so you can get details there.
When we do hierarchical clustering we get a dendrogram, this time of links, and once again we have to decide where to cut it. Modularity is defined for groups of nodes, so in the paper, we introduce a score for groups of links, partition density. A link community $c$ with $n_c$ nodes needs at least $n_c - 1$ links to hang together (a tree) and can have at most $n_c(n_c - 1)/2$ (a clique); its density is how far its $m_c$ links sit between the two, and $D$ averages that over the communities, weighted by their number of links:
$$D = \frac{2}{M}\sum_c m_c\,\frac{m_c - (n_c - 1)}{(n_c - 2)(n_c - 1)}$$
with $M$ the total number of links. In the 2010 paper we cut the dendrogram where $D$ is highest.
But with a brilliant student, I actually just updated and improved the idea. Here's what the new paper does. I realized that one cut height for the whole tree is a simplification. In the new paper we let every branch of the dendrogram have its own height (instead of a single cut) and that way we can get significantly better partition density and modularity across more than 200 real networks (Louis Boucherie, Yong-Yeol Ahn and Sune Lehmann, Adaptive cut reveals multiscale complexity in networks, arXiv:2512.08741).
Remember how we defined communities as densely interconnected with weak connections between communities. Highly overlapping communities are very different form that image. If every node is the member of many communities, then every community has more outgoing links than incoming ones. In a really interesting way, the network is locally super dense (the link communities are natually very clique-like), but can still be quite sparse at a global level. That means that link communities are especially suited for very dense networks. So if one wanted to analyze communties in the Marvel network, it might be worthwhile looking at link clustering over Louvain (see the explorable below). But don't link-cluster everything: Louvain is probably more appropriate for the philosophers ... and for any other network with visible network structure in the network plot.
Every block in the dendrogram is one link community, and every link on the network belongs to exactly one. Press Next community to walk through the teams (the X-Men, the Spider-Women, Blade's supernatural corner) and watch Spider-Man light up in 23 of them. One cut is the single height where $D$ peaks; Adaptive cut lets every branch choose its own, and the Goodies box explains it. Switch to Philosophers for Section 4's network.
What this explorable shows is also the weakness of most overlapping methods ($k$-cliques, link clustering). They are not great at parts of the network that are sparse and not overlapping. Those sparse parts end up with a lot of non-community nodes or single-community links. So they are effectively not assigned to any meaningful community. Sometimes that's a problem, sometimes it's not, depending on what you are trying to learn about the network. The overall lesson is that no tool is perfect, and you need to think and choose wisely.
Read
Network Atlas, Ch. 38 Overlapping Coverage, section 38.5 Clustering Links (the method below) and 38.7 The Overlap Paradox (the one-page surprise).
4.8 — Overlap on paper 🧠 Learn
Use the drawing from exercise 4.7, without the extra link B–D: triangles {A, B, C} and {C, D, E}, plus A–F.
- List the seven links. For each pair of links that share a node, say whether they belong to the same context (same triangle) or not, and group the links into link communities by eye. Which node ends up in two communities? Which link is in a community of its own?
- Compare with your $k = 3$ clique communities from 4.7. Where do the two methods agree, and what does the link method say about F that the clique method does not?
- Explain in two sentences why a node in two communities has a less dense neighborhood than a node in one, and what that does to a method that ranks nodes by neighborhood density.
- Name three overlapping communities you belong to and one person who is in exactly one of them. Where would a node partition of your friends put you, and what would it get wrong?
4.9 — Overlap or Infomap on the philosophers 🔬 Tool
Pick one of the two, run it on the philosophers' giant component, and compare with Louvain.
- Link communities. Have your agent implement link clustering from the description above: similarity between links sharing a node as the Jaccard score of the two other endpoints' inclusive neighborhoods (a node's neighbors plus the node itself), then single-linkage hierarchical clustering of the links, cut at the maximum partition density. Report how many communities Aristotle belongs to and name the five largest from their members. Then count the philosophers that belong to two or more communities: are they the hubs, or someone else?
- Infomap (the Goodies box explains it).
pip install infomap, run it on the same network, and report the number of modules and the NMI against your Louvain partition. Which groups do the two methods agree on, and which does one of them split? - 🔬 Either way, validate: take five philosophers your method puts in two communities (or moves between methods) and read their Wikipedia pages. Does the overlap or the disagreement correspond to something real about the philosopher? Keep the validation cell; it is the model for your project's
AI_METHODS.md.
7 · Weights: strong ties and weak ties
Phew. That's a lot of info on communities. Now take a break, a beat, a pause. Maybe a deep breath. Look up and focus your eyes away from the screen.
I'm asking for a pause because these last two parts are a whole new topic, that I'd also like to squeeze in before we get to the NLP part of the course.
Until now we have mainly considered unweighted networks. But before we wrap up the network part of the course, I want to put some tools and ideas about weighted networks on your radar.
Even though we've ignored it, the philosophers' edge file actually carries a weight on each link: the number of times A's article links to B's. Most pairs link once; a few link over and over, because the two philosophers' lives or ideas are entangled. Summed over both directions, the weights run from 1 to 24, while 5,899 of the 9,139 links have weight 1.
Weights change three things.
First, in weighted networks nodes have both degree and strength: $s_i = \sum_j w_{ij}$. Strength is just the sum of the total weight on a node's links. On the philosophers, strength and degree rank nodes almost identically (Spearman $0.96$; Aristotle leads both rankings with strength 521 based on a degree of 300). But the exceptions are the interesting part: Diogenes Laertius has only the 15th-highest degree (91) but the fifth-highest strength (230). If you're a philosophy buff, you'll realize that this is because his book Lives of the Eminent Philosophers is the source of a lot of knowledge about ancient philosophers, so the wiki articles of many ancient philosophers cite him again and again.
Second, the strongest ties often tell a story: Erasmus–Thomas More (24, close friends; Erasmus wrote The Praise of Folly in More's house), John Adams–Thomas Jefferson (22, fifty years of rivalry and letters, and death on the same day), Alfred North Whitehead–Bertrand Russell (19, Principia Mathematica). A weight of 24 between two pages says something a single link does not.
Third, paths are counted differently in weighted networks. Because a strong tie can be thought of as a short distance, network scientists often use $1/w_{ij}$ as the "length" of a link (and run an algorithm called Dijkstra's algorithm to estimate path lengths instead of BFS). David Hume and Karl Marx are two hops apart on the unweighted network, through any of 22 middlemen (Adam Smith, for one). The shortest strong-tie route between them is Hume → Kant → Hegel → Marx, one hop longer, over links of weight 7, 7 and 10. And it's not just shorter when you measure length as $1/w$, I'd argue that there's important information in the shortest weighted path: that's the route a history-of-philosophy lecture would take.
Weights and communities. Both modularity and Louvain can include weights without big changes. Simply replace $A_{ij}$ by $w_{ij}$, degrees by strengths, and $m$ by the total weight. Weighted Louvain on the philosophers finds 9 communities with a weighted $Q$ of $0.55$. That is higher than the unweighted $0.50$, but do not compare the two numbers: they are answers to different questions, and the strong ties concentrate inside groups almost by definition, so the weighted score has a higher ceiling. As always, to understand a value, compare it against the appropriate shuffled network.
For some reason that is not clear to me, the unweighted communities often seem more intuitive than the weighted ones, though.
Read
Network Atlas, Ch. 7 Extended Graphs, the part on weighted graphs; skim it. You met weights in week 1's adjacency-matrix explorable, and the philosophers file has them on every link.
4.10 — Weights by hand 🧠 Learn
Take the network from exercise 4.1 and give the links weights: A–B 3, A–C 1, B–C 4, C–D 1, D–E 2, D–F 5, E–F 2, F–G 1.
- Compute the strength of every node. Which node has the highest degree, which the highest strength, and are they the same?
- Find the shortest path from A to E by hops, then by weighted length with $1/w$ as the link length. Are they the same path? Say in one sentence what the weighted path "prefers."
- Compute the weighted modularity of the partition {A, B, C} · {D, E, F, G}: weights in place of link counts, strengths in place of degrees, total weight in place of $m$. Is it higher or lower than the unweighted $Q$ from 4.3, and why?
- A report says "the weighted modularity (0.55) is higher than the unweighted (0.50), so weights reveal stronger community structure." What is wrong with the sentence?
8 · Seeing structure in the hairball: backbones
Sune's quick take on backbones: why the hairball happens, the naive threshold and its failure, and the disparity filter with its null model.
Week 1 ended with a warning: a force layout of a big network is often an uninformative hairball. The presence of a hairball does not imply the absence of structure. It could be there because the network is so large that you can't calculate a good layout. It could be there because the network is full of overlapping communities. It could be there because there's a giant hub somewhere obscuring all the structure. Etc., etc.
By now you have the tools to dig into the hairball and understand the structure that it hides. But what if you want to visualize it anyway? Backbones are a way to begin to see structure in weighted networks that is obscured by many low-weight links.
A global threshold. If we start with philosophers, that network's giant component has 9,139 links. Most of them have weight 1, and a good fraction of those are a single passing mention on one page. If you could keep only the links that matter, the drawing would perhaps show some meaningful structure.
The set of links with large weights is the quintessential backbone of a network. The backbone of the most important links. This global threshold, where we keep every link with $w \ge 3$, for example, is quintessential, but also naive. And it has the problem that it throws away too much data.
On the philosophers that keeps 1,572 links and 863 philosophers. The problem is who it throws away. A weight of 2 is nothing for Aristotle (strength 521) and the strongest tie a minor philosopher has. A global threshold keeps a hub's fiftieth-strongest link and discards a small node's only meaningful one, so in many networks, the backbone based on weights becomes the hubs talking to each other, and everyone else disappears.
The disparity filter. In 2009 Serrano, Boguñá and Vespignani came up with an idea to fix this with yet another null model. But the twist this time is that the model is per node. In their model, for node $i$ with degree $k_i$ and strength $s_i$, each link carries a share $p_{ij} = w_{ij}/s_i$ of the node's strength. Serrano et al. compare that to the following null: the node's strength is spread over its $k_i$ links uniformly at random. Under that null, the probability that one link ends up with a share of at least $p_{ij}$ is $(1 - p_{ij})^{k_i - 1}$. That means that a link is significant for node $i$ when that probability is below a level $\alpha$ that we can adjust:
$$(1 - p_{ij})^{\,k_i - 1} < \alpha$$
To follow this algorithm, iterate over all nodes and keep a link if it is significant at either end.
Local importance. Take the weight-2 link between Aristotle and Moses of Narbonne, a 14th-century commentator on Averroes. For Aristotle it is 2 of 521, nothing. For Moses of Narbonne it is 2 of 11, spread over ten links: $(1 - 2/11)^{9} = 0.16$, below $\alpha = 0.2$, so the filter keeps the link, for his sake. Aristotle's own weight-2 ties, meanwhile, fail the test on his side (at $\alpha = 0.2$ a link needs more than 0.54% of his strength, a weight of 3 or more) and survive only when the other end needs them. The backbone contains important ties relative to each node, whether the node is big or small. Pretty great.
| α | links kept | philosophers with a link | giant component |
|---|---|---|---|
| 0.05 | 292 (3%) | 348 | 116 |
| 0.10 | 649 (7%) | 607 | 419 |
| 0.20 | 1,540 (17%) | 950 | 816 |
| 0.30 | 2,549 (28%) | 1,111 | 1,052 |
| 0.50 | 5,641 (62%) | 1,284 | 1,270 |
Disparity filter vs. thresholds. Compare $\alpha = 0.2$ with the $w \ge 3$ threshold: similar link counts (1,540 vs 1,572), but the disparity filter keeps 950 philosophers attached against 863. 112 philosophers (Moses of Narbonne among them) are attached by the filter and dropped by the threshold, and for every one of them the strongest tie is a 2: everything to them, nothing to the hub at the other end. Below $\alpha = 0.2$ the backbone comes apart: at $0.1$ the giant component is down to 419 philosophers, at $0.05$ to 116. There is no right $\alpha$; there is an $\alpha$ that you need to choose and the setting should depend on what you're trying to achieve. Be prepared to defend (or at least discuss) your choice.
Start at $\alpha = 0.20$: 1,540 links survive, 950 philosophers keep at least one, and the giant component holds 816 of them. Drag $\alpha$ down to $0.10$ and watch the giant component fall to 419 while the traditions pull apart. Then switch to Threshold at $w \ge 3$: a similar 1,572 links, but only 863 philosophers stay attached, and the tiles show what each filter threw away (at $\alpha = 0.2$ the strongest dropped tie has weight 6; at $w \ge 3$ a weight-2 tie between Aristotle and Isaac Newton is gone). Hover a faded philosopher to see which of their ties the filter took.
Some thoughts on network visualization. When you draw a network for your project (and for the rest of your life) I recommend you do it in this order ... and also make sure you document the steps in your report:
- Find the backbone first. If your network needs filtering (not all networks do), always use a method you've thought about and a parameter you can defend. And say how many links and nodes were removed.
- Then the layout. Create a layout of the backbone, not of the full network; the backbone is what makes e.g. a force layout work.
- Color by community. If the network has meaningful community structure (you know how to test if it does), based on a method that is appropriate (notes on how to do that above), it can enhance the visualization to show communities. But I generally advise against running community detection on the network backbone (unless you have a good reason to do so). The backbone isn't data (it's intended for visualization), instead pick a method that works for the data you have. Consider grouping the positions, and/or labeling the groups, because one reader in twelve cannot tell your green from your orange.
- Size by degree (or strength, or centrality), so what is important is visible without labels.
- Consider labeling important nodes so the reader can get oriented in the network.
Read
Network Atlas, Ch. 27 Network Backboning: the introduction, 27.1 Naive (the global threshold and what it breaks), 27.5 Disparity Filter (the method above); skim 27.3 and 27.6 for the other backbones.
4.11 — The backbone, and the figure 🔬 Tool
This figure is the rehearsal for Project B's data story.
- Load the weighted network, sum both directions, and compute strength for every philosopher. Plot strength against degree, log axes, and label Diogenes Laertius and the two or three other philosophers farthest from the diagonal.
- Implement the disparity filter from the formula above (no package, no
backboninglibrary): for each link, the significance at both ends, keep if either is below $\alpha$. Reproduce this page's table for $\alpha \in \{0.05, 0.1, 0.2, 0.3, 0.5\}$ and the $w \ge 2, 3, 4$ thresholds (3,240 / 1,572 / 785 links). Validate against the explorable's readout at $\alpha = 0.2$. - Draw the $\alpha = 0.2$ backbone following the five rules: force layout of the backbone only, nodes colored by Louvain community (computed on the full unweighted network) with a named legend, sized by strength, the ten highest-strength philosophers labeled, and a caption that states the filter, the parameter, and what was removed.
- 🔬 Draw the same figure at $\alpha = 0.1$ and $0.3$. Write three sentences on what the reader would conclude from each and which one you would put in a paper, and why.
4.12 — Ship an explorable 🚀 Builder · stretch, optional
The widgets on this page are a few hundred lines of vanilla JavaScript each (view source, nothing is hidden). Pick a claim from this week that none of them shows: a $k$-clique rolling across a toy network, Girvan–Newman's top-down dendrogram next to Newman's bottom-up one on the same network, link communities on a dozen-node toy with one node wearing two colors, the resolution limit (two cliques Louvain refuses to separate as the network around them grows), NMI between two partitions as you move nodes, the same backbone at three values of $\alpha$ side by side, and build the explorable that makes it grabbable, agents encouraged, taste yours. The best ones get embedded on this page with credit.
4.13 — Go nuts with your LLM 🚀 Builder · every week
The standing rules live in week 1, exercise 1.8: one free-form post on your group's site, link in this week's Teams channel by Monday evening, friendly criticism for at least one other group. Winner announced at 09:00 next Wednesday. This week the shared network is the philosophers (Marvel is fine too, if your group has a story going).
This week you have communities, overlap, weights and backbones. Some openers, if you want them:
- Louvain vs Infomap on the philosophers: run both, compute the NMI, and show the groups they disagree on as one figure. Which method tells the better history of philosophy, and can you say why in network terms?
- Which tradition is Aristotle really in? Link communities or k-cliques, a figure with his links colored by community, and an argument.
- The backbone at three values of $\alpha$ as one figure, with the giant component coming apart. Find the $\alpha$ at which it breaks and the philosopher whose links break it.
- Does the weighted network tell a different story than the unweighted one? Weighted vs unweighted communities, NMI between them, and the philosophers that move.
- Or ignore all of this and chase whatever the explorables made you wonder about. The winner is rarely the group that played it safe.
Standing option, weeks 2–4: crawl a different Wikipedia category of your own choosing (the API notes are in week 1) and run this week's toolkit there instead. Good rehearsal; your final project will live on a domain you pick.
Essentials
The 🧠 Learn core of the week: what a community is, cutting bridges, the number that scores a partition, the algorithms that climb it, the two checks you owe every result, two roads to overlap, weights, and the five drawing rules. All of it is pen-and-paper material; if a line below feels shaky, the section that teaches it is one click up the page.
- Community
- a set of nodes more densely connected among themselves than to the rest of the network. Coscia: if two nodes are in the same community, they are more likely to be connected. A partition assigns every node to exactly one community.
- Edge betweenness · Girvan–Newman
- edge betweenness is the number of shortest paths that run along a link (shared equally when a pair has several). Girvan–Newman (2002): remove the link with the highest edge betweenness, recompute every value, repeat; the network falls apart into groups, biggest cuts first. Slow: $O(m^2 n)$.
- Dendrogram
- the tree of groups a hierarchical method produces: one group at the root, single nodes (or links) at the leaves, one level per split or merge. Girvan–Newman builds it top-down (splitting), Newman's greedy method bottom-up (merging). Cut it at the level with the best score.
- Modularity $Q$
- $Q = \frac{1}{2m}\sum_{ij}\left(A_{ij} - \frac{k_ik_j}{2m}\right)\delta(c_i, c_j)$: the fraction of links inside communities minus what the degree-preserving null expects. Per community: $Q = \sum_c [\ell_c/m - (d_c/2m)^2]$ with $\ell_c$ the links inside $c$ and $d_c$ its members' summed degree. One community: $Q = 0$. Random assignment: $Q \approx 0$. It scores how grouped, not how right. Newman & Girvan (2004) introduced it to pick the level of a dendrogram.
- Greedy modularity (Newman 2004)
- start with every node alone; repeatedly merge the pair of communities whose merge raises $Q$ most; keep the level with the highest $Q$. Fast, but a merge is never undone.
- Louvain
- phase 1 move nodes: every node starts alone; visit nodes in turn and move each to the neighboring community that raises $Q$ most, until a sweep moves nobody. Phase 2 aggregate: each community becomes a super-node, crossing links become weighted links, repeat. Greedy, fast, and seed-dependent: the visiting order changes the result.
- Modularity of a random network
- not zero. A degree-preserving shuffle of the philosophers scores $Q \approx 0.23$ (Marvel: $0.25$), and the sparser the network, the higher: a random network with average degree 2 reaches $Q \approx 0.8$. Report a modularity against its null, as a difference or a $z$-score.
- Stability · NMI
- different seeds give different partitions with nearly equal $Q$ (philosophers: 8–10 communities, NMI 0.65–0.83 between runs; Marvel: 0.59). Normalized mutual information scores the agreement of two labelings: 1 = identical, 0 = independent. Use it against ground truth when you have it and between runs when you do not.
- k-clique community (clique percolation)
- Palla et al. 2005: two $k$-cliques are adjacent if they share $k-1$ nodes; a community is everything reachable by rolling from one to an adjacent one. Communities overlap, and nodes in no $k$-clique are in none. Small $k$ percolates into one giant; large $k$ leaves most nodes out. Software: CFinder.
- Overlapping communities · link communities
- real nodes belong to several groups; a partition must get all but one wrong. Link communities (Ahn, Bagrow & Lehmann 2010): cluster the links by the similarity of their endpoints' neighborhoods; each node inherits every community its links are in. Partition density $D$ picks the cut: each link community's density between a tree and a clique, averaged by its number of links. The overlap paradox: overlap nodes sit between groups, so density-based node methods rank them as the least community-like.
- Weight · strength
- a weight $w_{ij}$ on a link; strength $s_i = \sum_j w_{ij}$ replaces degree. Weighted distance: link length $1/w_{ij}$, shortest paths by Dijkstra. Weighted modularity: $w_{ij}$ for $A_{ij}$, strengths for degrees, total weight for $m$; not comparable to the unweighted value.
- Global threshold
- keep $w \ge \theta$. Keeps hubs' minor ties and drops small nodes' strongest ones; the backbone becomes the hubs alone.
- Disparity filter
- per-node null: node $i$'s strength spread uniformly over its $k_i$ links. With $p_{ij} = w_{ij}/s_i$, a link is significant for $i$ when $(1-p_{ij})^{k_i-1} < \alpha$; keep it if significant at either end. Keeps every node's own important ties. $\alpha$ is a choice you report.
- The five drawing rules
- backbone first, if the network needs filtering (a method you can defend, a parameter, say what was removed) → layout of the backbone, not the full network → color by community when the structure is real, detected on the full data, not on the backbone; group or label the groups, not color alone → size by degree, strength or centrality → label the important nodes. Document the steps in your report.
On Test 1
From this week, you should be able to do the following on paper, closed book. Any formula you need is printed on the test paper — you are never asked to write one from memory:
- define a community and a partition, and say what modularity measures and what it does not (how grouped, not how right);
- compute edge betweenness on a small drawn network by counting, say which link Girvan–Newman removes first, and explain why it recomputes after each removal;
- compute $Q$ for a given partition of a small drawn network with the per-community formula, compare two partitions, and state the value for "everything in one community"; (the formula is printed on the paper)
- describe Newman's greedy merging in words, and explain Louvain's two phases and why two runs on the same network differ;
- say why a random network has $Q > 0$, which null to compare against, and how to report a modularity honestly (difference from the null, or a $z$-score);
- read a score that compares two partitions (1 = identical, 0 = nothing in common — the normalized mutual information): what a high, a low and a middling value each say about how stable the community structure is, and why two Louvain runs differ at all;
- find the k-clique communities ($k = 3$) of a small drawn network, and name a node in two of them and a node in none;
- explain what an overlapping community is, why a node partition must miss it, and how clustering links recovers it;
- compute a node's total link weight (its strength) on a small weighted network, and find a weighted shortest path with $1/w$ as the link length;
- state what the disparity filter keeps that a global threshold does not, and apply the significance test to one link by hand;
- list the five drawing rules and spot the missing one in a described figure;
- spot the flaw in a short (possibly AI-written) claim about communities: a modularity with no null, a single run presented as the answer, or group names presented as findings.
Test 1 covers weeks 1–4
Wednesday 30 September in building 303A, Auditorium 42 or 43 (you will get an email telling you which): be there by 08:10, and the test runs 08:30–09:30 sharp. Pen and paper, closed book: 16 multiple-choice questions and 4 short written tasks. Everything on the test is in the four Essentials bands and their "On Test 1" lists: week 1 · week 2 · week 3 · week 4. The 🧠 exercises of each week are the shape of the questions; the ones you found hard are the ones to redo.
Goodies
Everything above is the course. Everything below is for the student who finished the page and wants more. Nothing here is on the test; all of it is worth your time.
The resolution limit
Modularity has a blind spot with a formula. Santo Fortunato and Marc Barthélemy showed in 2007 that maximizing $Q$ will merge two connected communities whenever each has fewer than about $\sqrt{2m}$ internal links, no matter how clearly separated they are. The reason is in the null term: the expected number of links between two small groups, $d_ad_b/2m$, shrinks as the network grows, so a single link between them eventually counts as "more than expected" and merging them raises $Q$. On the philosophers, $\sqrt{2m} \approx 135$. Every one of the big traditions is far above that (the smallest, the Chinese community, has 234 links inside), but a tight school like the Legalists, nine philosophers with 27 links among them (a $k = 5$ clique community in Section 5), is far below it, and Louvain folds it into the Chinese community. The fix is a resolution parameter $\gamma$ multiplying the null term (resolution= in networkx's Louvain): $\gamma > 1$ finds smaller communities, $\gamma < 1$ larger ones (on the philosophers, $\gamma = 2$ gives 16 communities instead of 9), and a partition that is stable across a range of $\gamma$ is one to believe. There is no "true" resolution, only a reported one.
Leiden: the fix for Louvain's broken communities
Louvain has a documented defect: a community can end up disconnected. In phase 1 a node that was the bridge between two halves of its community can move away, leaving the two halves labeled as one group with no link between them, and phase 2 then glues them together forever. Vincent Traag, Ludo Waltman and Nees Jan van Eck showed in 2019 that on real networks a noticeable share of Louvain communities are badly connected, and proposed Leiden: the same two phases plus a refinement step between them that splits every community into its connected, well-linked parts before aggregating. It is as fast as Louvain, it guarantees connected communities, and it usually finds a slightly higher $Q$. pip install leidenalg (or igraph's built-in) and use it as your default; when you say "Louvain" in a paper today, you probably mean Leiden.
Infomap: communities as a compression problem
Modularity is not the only way to make "more likely to be connected" precise. Martin Rosvall and Carl Bergstrom, in 2008, asked a different question (Martin tells the story of the method, and of how the map equation got its name, on my podcast): put a random walker on the network and describe its path as compactly as possible. If the network has groups, the walker lingers inside one for a long time before crossing, so you can save bits with a two-level code: a short codeword for "which module am I in," then short codewords for nodes within the module, reused across modules the way street names are reused across cities. The best partition is the one that gives the walk the shortest description; the formula for that length is the map equation, and the algorithm that minimizes it is Infomap. It has three properties you will care about. It handles directed networks natively, as a walk does, where modularity has to be adapted. It does not have the resolution limit in the same form. And it agrees with Louvain often enough that disagreement between the two is worth reading. Make Infomap the second algorithm you always run; Louvain vs Infomap on the philosophers, with an NMI and the disputed groups drawn, is one of this week's go-nuts openers. Atlas 35.2.
Stochastic block models: communities as a generative model
Everything on this page scores partitions. The stochastic block model turns the problem around: assume the network was generated by a model in which each node has a block label, and the probability of a link between two nodes depends only on their two blocks (a $B \times B$ matrix of probabilities). Fit the model, and the block labels are the communities. The elegance is that "community" no longer has to mean "dense inside": if the matrix has large diagonal entries the blocks are assortative communities, but if the off-diagonal entries are large you get a core–periphery structure (one block links to everyone, the other only to the core) or a bipartite-like one, and the same method finds all of them. Modern versions choose the number of blocks by description length, avoiding the resolution limit, and give you a posterior over partitions instead of one answer. Tiago Peixoto's graph-tool is the reference implementation; Atlas 35.1 has the model.
Peixoto's war on modularity
Not everyone thinks the checks in Section 4 are enough. Tiago Peixoto, professor of network science at Goethe University Frankfurt and the author of graph-tool, has argued for years, with a good deal of fire, that modularity maximization should be retired. His blog post Modularity maximization considered harmful (2021) is the short version, and its charges are the ones you met on this page, pushed to their conclusion. It overfits: it finds communities in networks generated by its own null model (the $0.23$ on a shuffled philosopher network, the $0.8$ on a sparse random one), because the null describes a network before an optimizer has searched a space of partitions with 2,804 digits for the best-looking one. It underfits: the resolution limit two boxes up caps a connected network at about $\sqrt{2m}$ communities, whatever the network contains. And its landscape is degenerate: many partitions share nearly the same $Q$ (the NMI of $0.65$–$0.83$ between runs), so even the true maximum would not be the answer. His verdict is that modularity is a descriptive method being used for an inferential question ("what groups generated this network?"), and that comparing to a null afterward cannot repair that.
What he proposes instead is the stochastic block model from the box above, fitted by Bayesian inference: write down the probability of the observed network given a partition, put a prior on partitions that charges for every extra block (the minimum description length principle, Infomap's compression idea applied to the model rather than to a random walk), and look for the partition with the highest posterior probability. On a random network this returns one block, because no partition describes the network better than "no structure," so the overfitting is gone by construction; the hierarchical version has no resolution limit of the $\sqrt{2m}$ kind; and you get a posterior distribution over partitions, so "how stable?" has an answer built in. The full argument is his 2023 book, Descriptive vs. Inferential Community Detection in Networks: Pitfalls, Myths and Half-Truths (Cambridge Elements; the arXiv version is free), and the tutorial Bayesian Stochastic Blockmodeling is the math. To run it, graph-tool's inference how-to goes from a first minimize_blockmodel_dl(g) to hierarchical models and posterior sampling (install with conda install -c conda-forge graph-tool; there is no pip package). One thing to know before you press the button: a plain SBM finds any block structure, not only groups that are dense inside, so the blocks it hands you may be a core and a periphery rather than communities; the how-to's section Assortative community structure has the variant that looks for the kind of groups this page is about.
Where does that leave this page? Peixoto is right about the failure modes, and the two habits Section 4 insists on (a null and a stability check) exist because of them. Modularity is still what you will meet in nearly every paper and every library, and a Louvain partition reported against its null, with an NMI between runs, is an honest descriptive summary of a network. When the question is whether the groups are real, run the SBM too; if the two disagree, you have learned something.
The adaptive cut: let every branch choose its own height
Section 6 cut the link dendrogram at the one height where the partition density $D$ peaks, and the explorable there has an Adaptive cut button. The adaptive cut (Louis Boucherie, Yong-Yeol Ahn and Sune Lehmann, arXiv:2512.08741; code) drops the one-height constraint: any set of branches that together cover every link is a valid cut, and a random walk on the dendrogram looks for the best one, moving a community's cut one merge up or down and accepting the move if $D$ rises, and sometimes if it falls, less and less often as the walk cools (Metropolis–Hastings with simulated annealing). It is "the best we found," not "the best there is."
On the philosophers $D$ goes from 0.054 to 0.081 and the communities of three links or more from 444 to 682; on Marvel, from 0.110 to 0.143 and from 82 to 139. The walk moves in both directions. Up, to a coarser cut: Christian scholasticism, in fragments at the single height (Aquinas with Bonaventure in a 38-link piece, Duns Scotus in an 11-link one), becomes one 113-link community. Down, to a finer one: the single 118-link German community splits into the idealists (Kant, Fichte, Schelling, Hegel) and the later academics (Wundt, Lotze, Herbart). The gain is largest on lopsided dendrograms, a few huge branches and thousands of tiny ones, which is what both networks have.
Don't read too much into how many communities a node is in: that number tracks degree (Spearman 0.83), so it mostly says "hub." Communities per link is the more telling ratio: Kepler is in 17 communities from 28 links, a bridge between astronomy, theology and philosophy, while Jesus is in 3 from 70 and Ptolemy in 1 from 38, hubs everybody links to from one direction; on Marvel, Iron Fist is in 14 from 26 and She-Hulk in 2 from 37. And the walk is stochastic and touchy about its temperature: too warm and it merges everything into two communities; at the right setting, eight runs landed between $D = 0.068$ and $0.081$. Every number is in tools/groundtruth/week4_adaptive_cut.py.
Other backbones
The disparity filter is one null model among several, and Atlas Ch. 27 walks through the alternatives. The high-salience skeleton (Grady, Thiemann and Brockmann 2012; Dirk Brockmann is an episode of my podcast, on mobility and epidemics) keeps a link if it lies on the shortest-path tree from most nodes, a global criterion where the disparity filter is local. The noise-corrected backbone is Coscia's own (Coscia and Neffke 2017): it models each weight as a draw from a distribution whose mean is what the two endpoints' strengths predict, and keeps links whose weight is surprisingly high given that expectation, which behaves better than the disparity filter when strengths are very unequal. And the simplest defensible one for a sparse network is the doubly stochastic filter, which rescales the weights until every row and column sums to one and then thresholds. The lesson is the same as the week's: name the null, name the parameter, say what was removed.
Reading: the club, the methods, the links, the backbone
- Wayne W. Zachary, An Information Flow Model for Conflict and Fission in Small Groups, Journal of Anthropological Research 33 (1977). The original; the network is in a figure and the prediction is the paper's point.
- Michelle Girvan & Mark E. J. Newman, Community Structure in Social and Biological Networks, PNAS 99 (2002). The paper that started the field, five pages; Section 2.
- Mark E. J. Newman & Michelle Girvan, Finding and Evaluating Community Structure in Networks, Physical Review E 69 (2004). Where modularity comes from; Section 3.
- Mark E. J. Newman, Fast Algorithm for Detecting Community Structure in Networks, Physical Review E 69 (2004). Greedy merging; the
networkxversion is the faster implementation by Aaron Clauset, Mark Newman and Cristopher Moore, Physical Review E 70 (2004). - Vincent D. Blondel, Jean-Loup Guillaume, Renaud Lambiotte & Etienne Lefebvre, Fast Unfolding of Communities in Large Networks, Journal of Statistical Mechanics (2008). The Louvain paper; the two phases are a single figure.
- Roger Guimerà, Marta Sales-Pardo & Luís A. Nunes Amaral, Modularity from Fluctuations in Random Graphs and Complex Networks, Physical Review E 70 (2004). Why a random network has modularity.
- Gergely Palla, Imre Derényi, Illés Farkas & Tamás Vicsek, Uncovering the Overlapping Community Structure of Complex Networks in Nature and Society, Nature 435 (2005). Clique percolation; Section 5.
- Yong-Yeol Ahn, James P. Bagrow & Sune Lehmann, Link Communities Reveal Multiscale Complexity in Networks, Nature 466 (2010). Section 6, by one of the authors.
- Louis Boucherie, Yong-Yeol Ahn & Sune Lehmann, Adaptive Cut Reveals Multiscale Complexity in Networks, arXiv:2512.08741 (2025). Cutting a dendrogram at a different height in every branch.
- M. Ángeles Serrano, Marián Boguñá & Alessandro Vespignani, Extracting the Multiscale Backbone of Complex Weighted Networks, PNAS 106 (2009). The disparity filter; four pages.
- Santo Fortunato, Community Detection in Graphs, Physics Reports 486 (2010). The review of the whole field, a hundred pages; read the introduction and dip in. The 2016 update with Darko Hric, Community Detection in Networks: A User Guide, is the shorter one.